
Understand AI engineering—and choose a small project
AI engineers turn models into useful software. Depending on the role, you might prepare data, connect a model to an application, evaluate predictions, or keep a deployed service reliable. You usually work with existing models rather than inventing new architectures. Programming, debugging, and making sensible trade-offs matter as much as understanding model behavior.
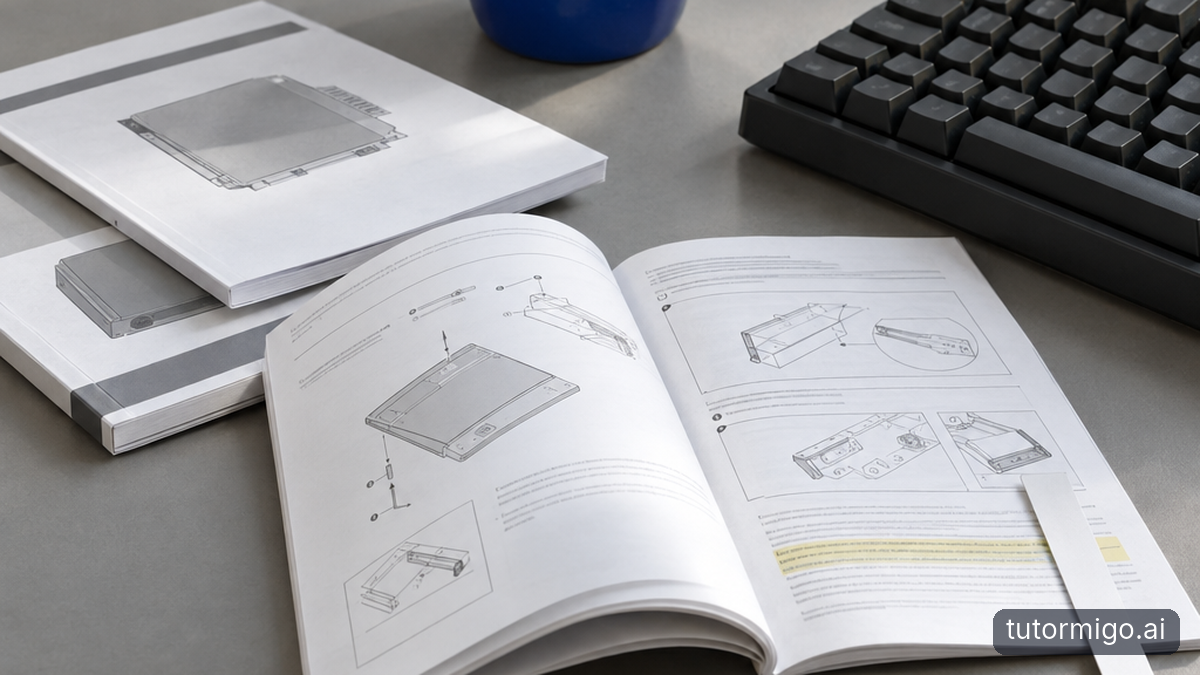
For your first project, build an app that answers questions about a small collection of documents and shows supporting passages. Imagine using three public equipment manuals: someone asks how to reset a device, and your app returns instructions with a source reference. That gives you a concrete problem without requiring a huge dataset or training budget. Choose readable text documents first; scanned PDFs introduce optical character recognition problems you do not need yet.
Define success before choosing tools. Your first version should accept a question, retrieve relevant text, produce a grounded answer, and decline when the documents lack evidence. Leave out user accounts, autonomous agents, and multiple file formats. Each milestone should leave you with something runnable, even if it is only a terminal program. This scope teaches the full engineering loop without turning your first project into an unfinished platform.
Build practical Python and SQL foundations
Start with Python values, strings, lists, dictionaries, loops, functions, and imports. Then learn file handling, exceptions, virtual environments, and package installation. You are ready to progress when you can read several text files, clean their contents, and return matching passages for a search term. You do not need advanced inheritance or clever one-line solutions.
Practice debugging deliberately. Read tracebacks, inspect intermediate values, and write small tests for functions that split documents or preserve source names. Learn Git early enough to save working versions and undo experiments. Your first milestone is a command-line document search tool with repeatable setup instructions. Use Python’s standard library where possible; add a package when you can explain what problem it solves.
For SQL, focus on selecting and filtering records, sorting results, joining tables, and grouping data. SQLite is enough to practice locally. Store document metadata in one table and question attempts in another, then investigate which documents receive questions or which requests fail. Keep private question text out of logs unless you have a clear reason and permission to retain it.
You can learn these skills together. Import document metadata, query it, and inspect the results in Python. That workflow builds useful fluency faster than finishing disconnected courses before touching a project.
Learn the math and machine learning you will actually use
You need mathematical understanding, not a mathematics degree, to start building. Prioritize vectors, matrices, dot products, and similarity: these explain how text embeddings represent passages and help find related material. Learn basic probability, averages, variation, and sampling so you can interpret results without mistaking a few good examples for reliable performance.
Next, understand features, labels, training, inference, overfitting, and the difference between training, validation, and test data. Train one simple classifier with scikit-learn on a small public dataset. Compare it with a basic baseline, inspect mistakes, and explain why accuracy alone can mislead when one class dominates. Keep preprocessing fitted on training data rather than accidentally learning from your test set.
This exercise teaches the experimental habits your document app needs, even though you will not train its language model. You will still choose settings, compare alternatives, and reserve questions for a final check. Learn what gradients and loss functions mean conceptually; deeper calculus becomes more important if you later train or fine-tune neural networks.
Move forward when you can explain a model’s inputs, outputs, evaluation method, and likely failure modes in plain language. Do not postpone application building until you have mastered every algorithm.
Add APIs and language models after local search works
Learn APIs once you can write and debug a local Python program. Understand HTTP requests, JSON responses, authentication, timeouts, and common error codes. Start with one model provider’s client library or a straightforward HTTP client. Keep credentials in environment variables, never in source control or browser code, and set spending limits where available.
Now evolve your search tool into retrieval-augmented generation, often called RAG. Split documents into passages while preserving their source and location. Generate embeddings, store them, and retrieve relevant passages for each question. Send those passages and the question to a language model with instructions to answer only from the supplied evidence. A model’s general knowledge is not proof that an answer appears in your documents.
Your second milestone is a terminal app that returns an answer and usable citations. For a tiny collection, a local embedding index or even an initial keyword-search baseline is sufficient. You do not need a managed vector database, an orchestration framework, and an agent framework simultaneously.
Keep Python, one model client, and one retrieval approach as your core toolkit. Add a simple interface with Streamlit when the pipeline works. Treat document content as untrusted data: embedded instructions must not override your application’s rules, and the app should not execute actions requested by retrieved text.
Evaluate the answers, then deploy a modest version
Before deployment, create a fixed set of questions with expected supporting passages. Include straightforward lookups, questions requiring two passages, ambiguous wording, and questions the documents cannot answer. Record retrieval success separately from answer quality. If the correct passage never reaches the model, rewriting the answer prompt will not fix the underlying problem.
Check whether answers are supported, citations actually contain the claimed information, and refusals happen appropriately. Track response time and approximate cost per question. Run the same questions after changing passage size, retrieval settings, or models. Keep some questions untouched until your final comparison so you do not optimize entirely for familiar examples. A fluent answer is not automatically a correct one.
Your third milestone is a small deployed app with clear limitations. Choose hosting that supports your interface, pin dependencies, configure secrets on the host, and test installation from a clean environment. Confirm whether the service preserves local files between restarts. Add request timeouts, input-size limits, and friendly errors when the model service is unavailable.
Use public or permissioned documents and check any provider’s data-handling terms before sending content. For a public demo, restrict uploads or disable them initially, limit requests, and monitor spending. Deployment is successful when another person can use the app safely and you can diagnose failures—not merely when a page loads.
Choose your starting point and take the next step
If functions and file handling still feel unfamiliar, start by reading one text document and finding paragraphs containing a search term. If you can already do that comfortably, add metadata storage and a basic retrieval test. If you know Python and APIs, begin with the evaluation questions before connecting a language model. Your starting point should follow demonstrated ability, not how many tutorials you have watched.
Write a one-page project plan today: the documents you will use, the questions your app should answer, what it must refuse, and how you will check success. Break delivery into three checkpoints: working local search, grounded answers with citations, and a deployed demo. Give each checkpoint an acceptance test, such as returning the correct source passage for a known question. Set dates around your available practice time rather than promising mastery in a month.
For your portfolio, include setup instructions, an architecture sketch, evaluation results, known weaknesses, and one failed approach you improved. Those details show engineering judgment more convincingly than a polished screenshot. If you want extra Python practice along the way, TutorMigo.ai offers browser-based coding challenges organized by language and difficulty.
Frequently asked questions
No degree is required to begin building projects. Hiring requirements vary, but programming fluency, sound evaluation, and clear explanations of your work give you concrete evidence of your skills.
No. Start with an existing model and learn retrieval, evaluation, and deployment. Training a language model introduces substantial data, computing, and infrastructure demands.
Not if you use a hosted model API and lightweight local retrieval. Running models locally may require more memory or specialized hardware, depending on the model.
Enjoyed this read?
Like, share, or comment below.
Comments
0Sign in required · respectful discussion · replies supported
Loading comments…